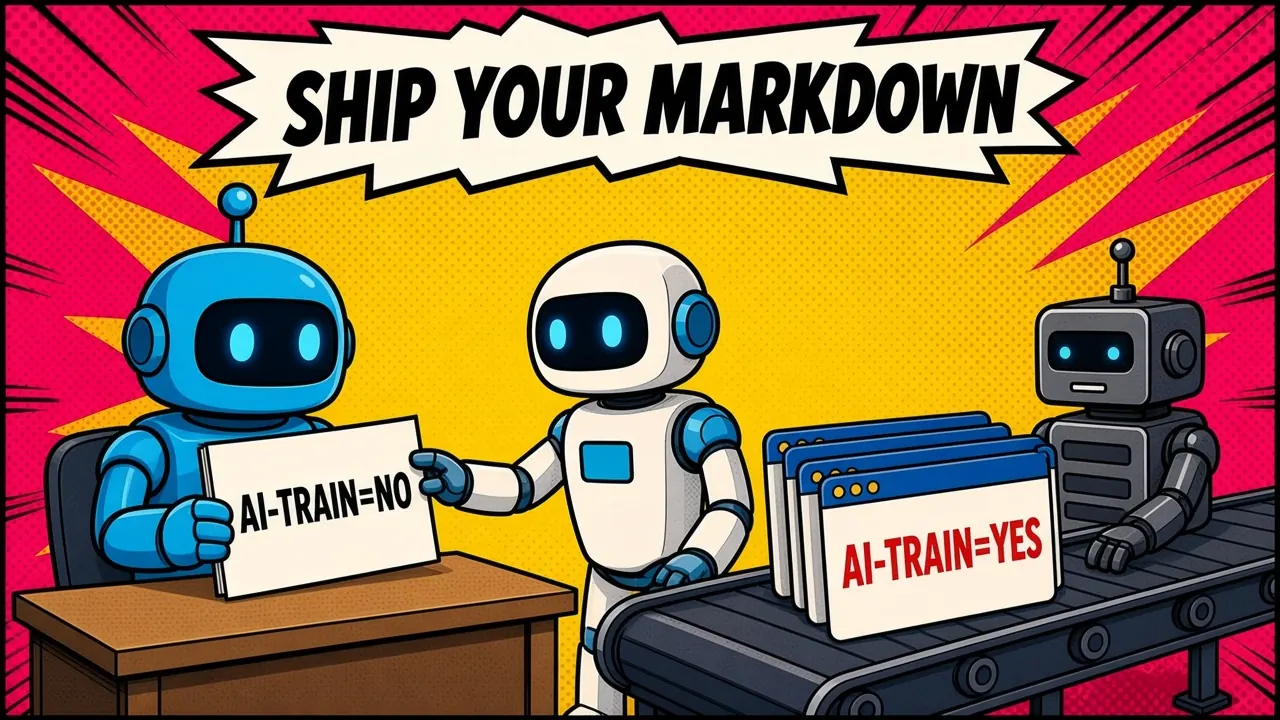
If you turn on Cloudflare’s Markdown for Agents and never set a Content-Signal at the origin, the converted response says ai-train=yes.
I run this site on Cloudflare Pages. I want agents to read the posts I wrote, and I do not grant training rights. A converter is useful when all you have is HTML. It is not a substitute for a file you published and a policy you stated.
What became generally available
The 9 November 2026 changelog says Markdown for Agents is generally available. The same entry adds tools to watch conversions: Analytics and Logs in the dashboard, a Playground that requests Markdown for a path on your zone, the GraphQL dataset markdownForAgentsAdaptiveGroups, and a markdown_conversion span in Cloudflare Traces.
The feature documentation (updated the same day) describes the contract. On an enabled zone, a client that sends Accept: text/markdown can get a Markdown body. Cloudflare fetches the HTML from the origin and converts it. The response uses Content-Type: text/markdown; charset=utf-8, and Vary includes Accept.
The same page lists the limits that matter in production. Conversion is capped at 6 MiB (6,291,456 bytes) of decompressed HTML. Analytics cover at most seven days. Token savings are estimated from bytes divided by four, and only from full conversions, not from a real tokenizer.
The docs say the feature is available on Pro, Business, and Enterprise plans, and to SSL for SaaS customers, at no cost. I am not guessing whether a given Pages project is on one of those plans. If your zone has the toggle, this is the contract behind it.
The default signal is the part that bites
Markdown for Agents does more than change the body. It also sends a Content-Signal.
The current docs are clear. If your origin already sets a content-signal header, the converted response keeps that value. If the origin does not send one, Cloudflare adds Content-Signal: ai-train=yes, search=yes, ai-input=yes.
That default is not new. The 12 February 2026 announcement, when the feature was in beta, already showed the all-yes header on the example response. The 13 July 2026 changelog made the origin header authoritative. Silence at the origin still becomes all yes.
Content Signals
If you omit a key, you neither grant nor restrict that use. A missing signal is not a yes, and it is not a no.
Cloudflare's converter
If the origin sends no content-signal header, the converted Markdown gets
ai-train=yes, search=yes, ai-input=yes.
Content Signals is Cloudflare’s implementation of a way to declare how automated systems should use your content after they have accessed it. The three keys are specific:
searchis building a search index and providing search results, such as hyperlinks and short excerpts. It does not include AI-generated search summaries.ai-inputis feeding the content into a model, including RAG, grounding, or other real-time use as input.ai-trainis training or fine-tuning a model.
The same page says this is a preference. robots.txt cannot technically prevent a crawler from taking the content, and some operators ignore it. State the preference anyway. If you leave the header off and then enable the converter, Cloudflare fills the silence with yes.
A missing Content-Signal is not a yes. Cloudflare’s converter still adds one.
What I ship at the origin
I did not want a converted guess at a post. I wanted the Markdown I wrote, at a stable URL, with a policy I chose.
robots.txt on this site is:
User-agent: *
Content-Signal: search=yes, ai-input=yes, ai-train=no
Allow: /
Disallow: /styleguide/

Sitemap: https://ansezz.com/sitemap-index.xml
Agents may use the pages for search and as input. They may not use them to train. That is the preference I am willing to put in public.
The Markdown is a pre-built twin, not an HTML conversion at request time. A Cloudflare Pages Function in functions/_middleware.ts looks at Accept. When the client prefers text/markdown, it serves the file written into the build.
/ maps to /index.md, and /about/, /contact/, and /blog/ each have an index.md. Each post lives at /blog/<slug>/index.md. Direct .md URLs stay files. If a twin is missing, the HTML page is served instead of a 404.
That layout follows the llms.txt proposal (v2, updated 10 August 2026): a Markdown version of a page at index.md, advertised with rel=alternate and type=text/markdown, and an llms.txt file advertised with rel=describedby.
The HTML responses add a Link header for those relations, plus rel=canonical. /llms.txt is the short map. /llms-full.txt is the longer companion, with the full Markdown of the home page, about, contact, the blog index, and every post.
I checked the live site on 14 November 2026, at 9:25pm Asia/Kuala_Lumpur. A HEAD to https://ansezz.com/ with Accept: text/markdown returned content-type: text/markdown; charset=utf-8 and vary: Accept.
The body starts with the page title, then Canonical and Markdown links. It is not the YAML frontmatter that Cloudflare’s converter builds from meta tags, and it is not a JSON-LD fence appended at the end.
The response header matches robots.txt
The same live check, on 14 November 2026, showed no Content-Signal HTTP header on the HTML or the Markdown responses. The policy was in robots.txt only.
That was a real gap. The Agent Readiness Checker reads the Content-Signal line from robots.txt. A pass there does not mean the response header is set.
If the converter ran on a path that still returns HTML, and the origin sent no header, the converted body would get ai-train=yes. That would contradict the robots.txt line.
The origin now sends the same policy on HTML and Markdown responses:
Content-Signal: search=yes, ai-input=yes, ai-train=noA client that asks for text/markdown, and a client that opens the .md URL, both get that header. It matches robots.txt.
Check the live site, not the dashboard toggle
A toggle in a dashboard does not tell you what an agent actually receives. The headers do.
curl -sI -H "Accept: text/markdown" https://example.com/
curl -s https://example.com/robots.txt
curl -s https://example.com/llms.txt
Read Content-Type, Vary, Content-Signal, and the Link header. Then open the body and see whether it looks like a file you wrote, or like a conversion of the HTML.
You can also paste the URL into the Agent Readiness Checker. It fetches the public URL you submit, does not store the report, and checks Markdown negotiation, the stable .md URL, Link headers, llms.txt, llms-full.txt, and the robots.txt Content-Signal, along with the usual access checks.
Use the Content site type unless you really have an API or a store. MCP, OpenAPI, and commerce discovery are shown either way. They only count toward the score when they apply. Do not publish a fake catalog to close a gap.
Key takeaways
- Markdown for Agents is generally available. It converts HTML when a client
asks for
text/markdown. If the origin sends noContent-Signal, the converted response saysai-train=yes. - That all-yes default is Cloudflare’s, not the Content Signals default. A missing key is an unstated preference. Statesearch,ai-input, andai-trainin robots.txt and on the response header. - I ship authored Markdown twins, Link headers, and llms.txt from the origin. robots.txt and the response header both sayai-train=no. The checker reads the robots.txt line.
If an agent asked your homepage for Markdown tomorrow, would it get a file you wrote, and would the signal say it may train on it?