▸ Blog · Page 8
More from the trenches.
Older posts. Same hot takes.
-
 DevOps
CI vs CD: automating quality and delivery
Continuous Integration vs Continuous Delivery explained. How to automate the path from commit to production for Laravel backends and Shopify storefronts.
Read post →
-
 Architecture
API vs MCP: connecting AI systems
The core differences between traditional APIs and the Model Context Protocol (MCP), and when to use each to build scalable, agentic AI systems.
Read post →
-
 DevOps
Ditch expensive cloud providers for self-hosted SaaS
The cloud tax kills SaaS margins early. How self-hosted Coolify on cheap ARM instances at Hetzner or Oracle slashes a $500 AWS bill toward zero.
Read post →
-
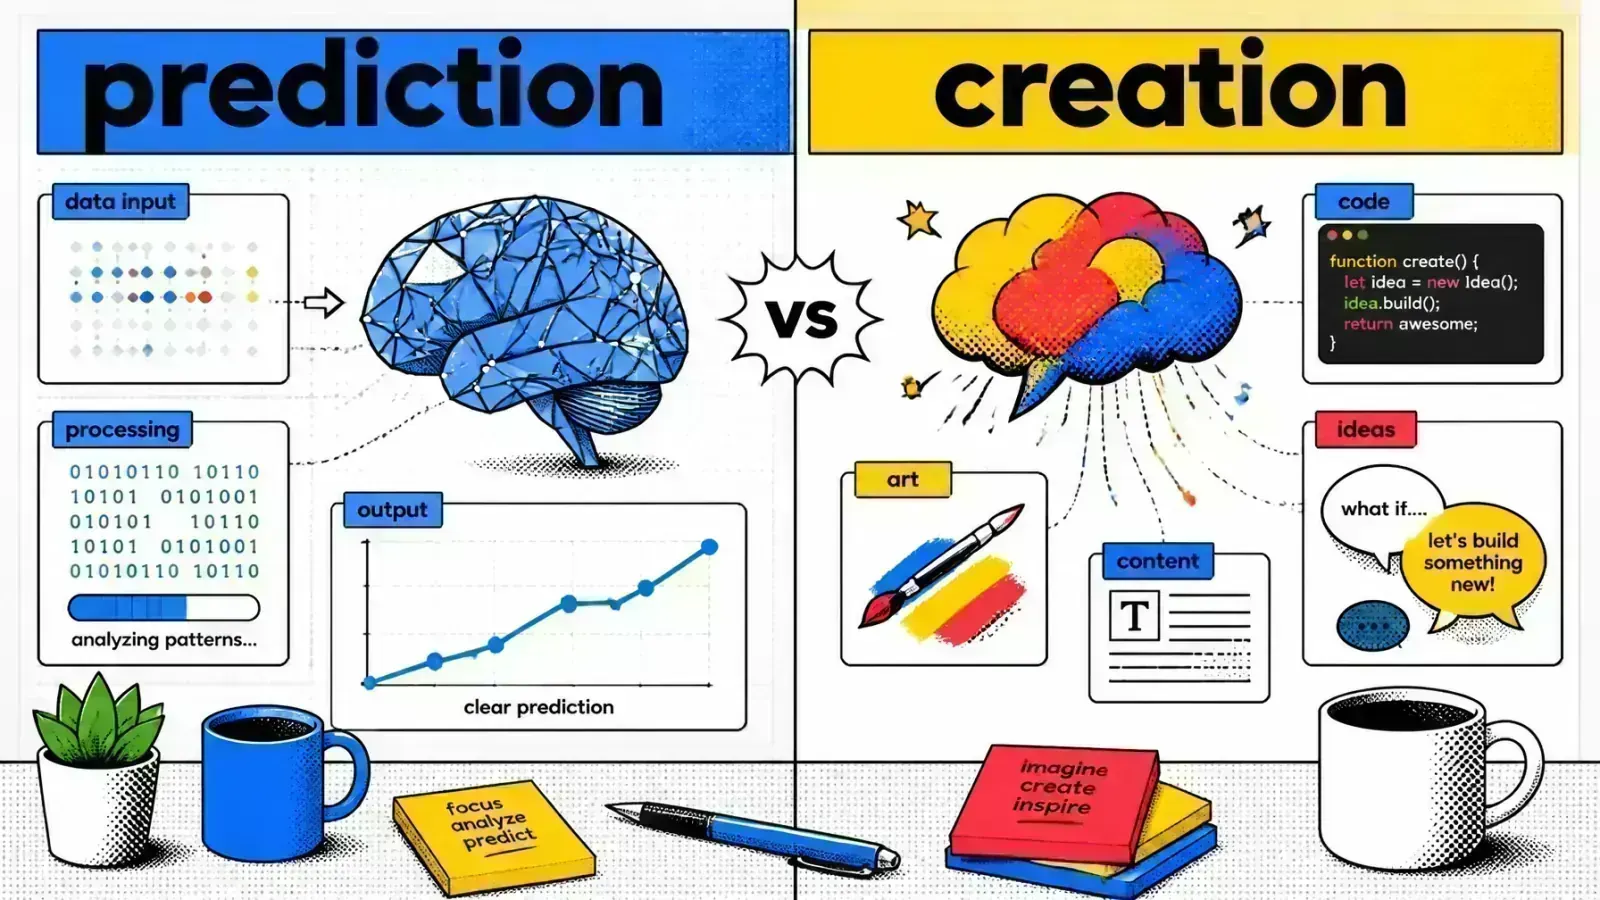 AI
Machine learning vs generative AI
Machine Learning predicts; Generative AI creates. The discriminative-vs-generative split decides your architecture, infra, and monthly cloud bill.
Read post →
-
 Laravel
 Octane for high-traffic PHP apps
Laravel Octane boots your app once and keeps it warm in memory, feeding requests through a worker pool. How to cut boot overhead and scale to high traffic.
Read post →
-
 Shopify
 UCP quick-start: make your store agent-ready
AI agents are becoming buyers, and they look for a UCP profile before they can check out. A quick-start to making your Shopify store agent-ready.
Read post →
-
 AI
Claude MCP: connecting my dev tools to LLMs
The Model Context Protocol is a USB-C port for LLMs: one MCP server, any host, no MxN integration tax. The architecture, the servers I run, and why it is safe.
Read post →
-
 Architecture
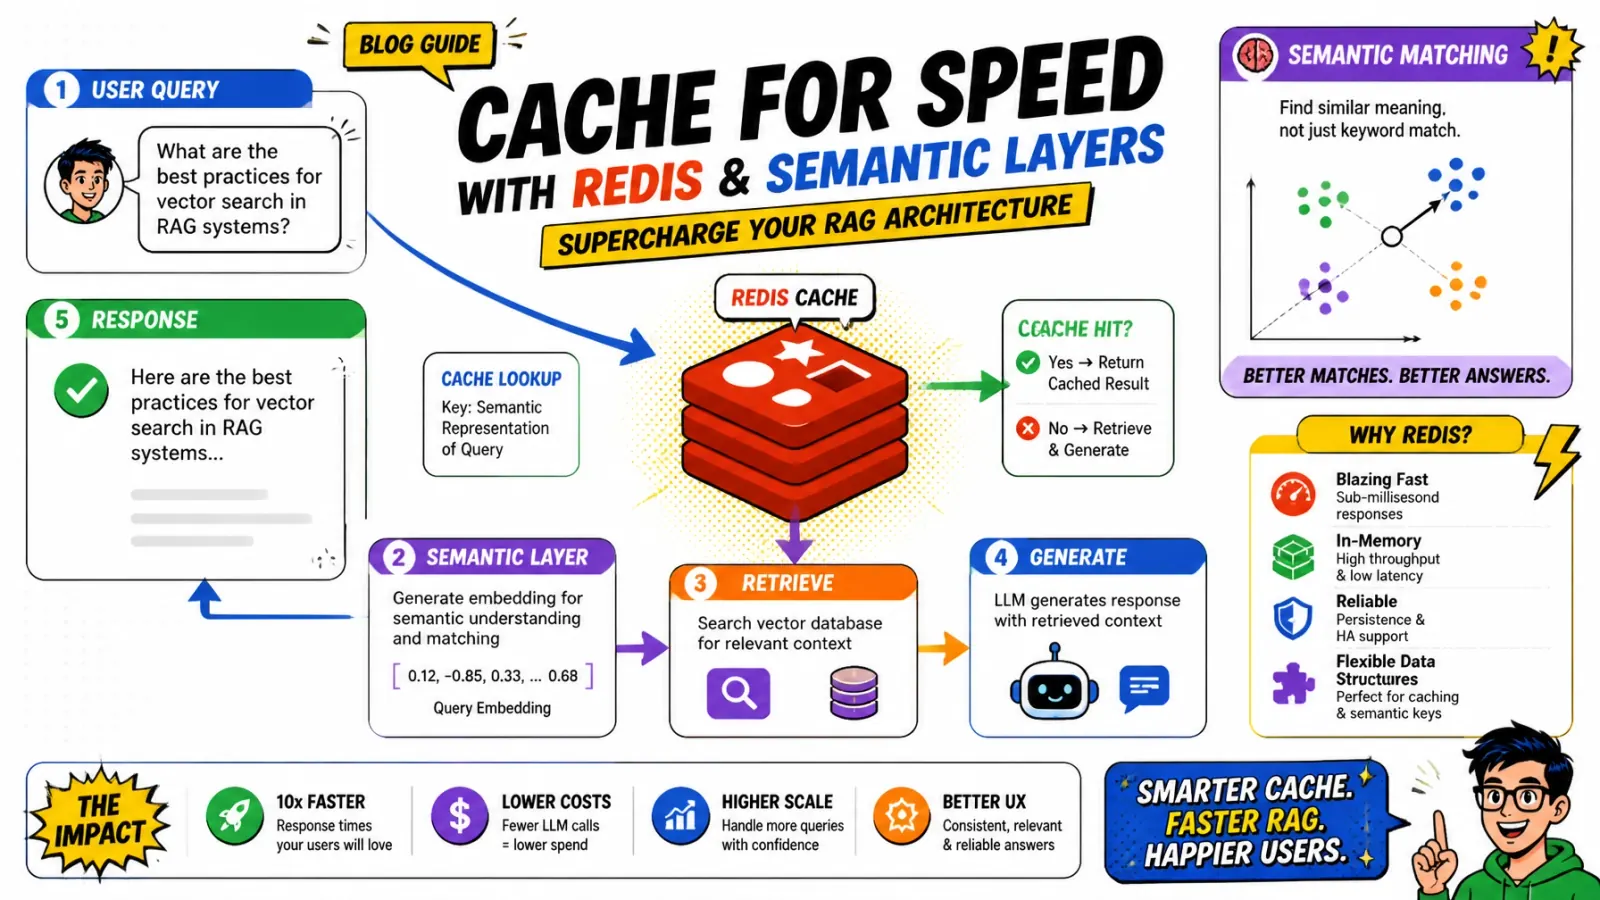
Caching for speed: Redis and semantic layers in RAG
Stop paying for the same LLM call twice. Two-tier caching with Redis keys and RedisVL semantic lookups slashes RAG latency and trims your LLM API bill.
Read post →
-
 Architecture
Smart auto-scaling for modern AI apps
CPU auto-scaling fails GPU workloads. Why queue depth, KV-cache pressure, and TTFT beat CPU as triggers, plus the KEDA patterns to scale AI in time.
Read post →