▸ Tag · #vector-search
Vector search.
Vector and hybrid retrieval — pgvector, Pinecone, Weaviate, Qdrant, graph search, and choosing one without regretting it six months later.
-
 AI
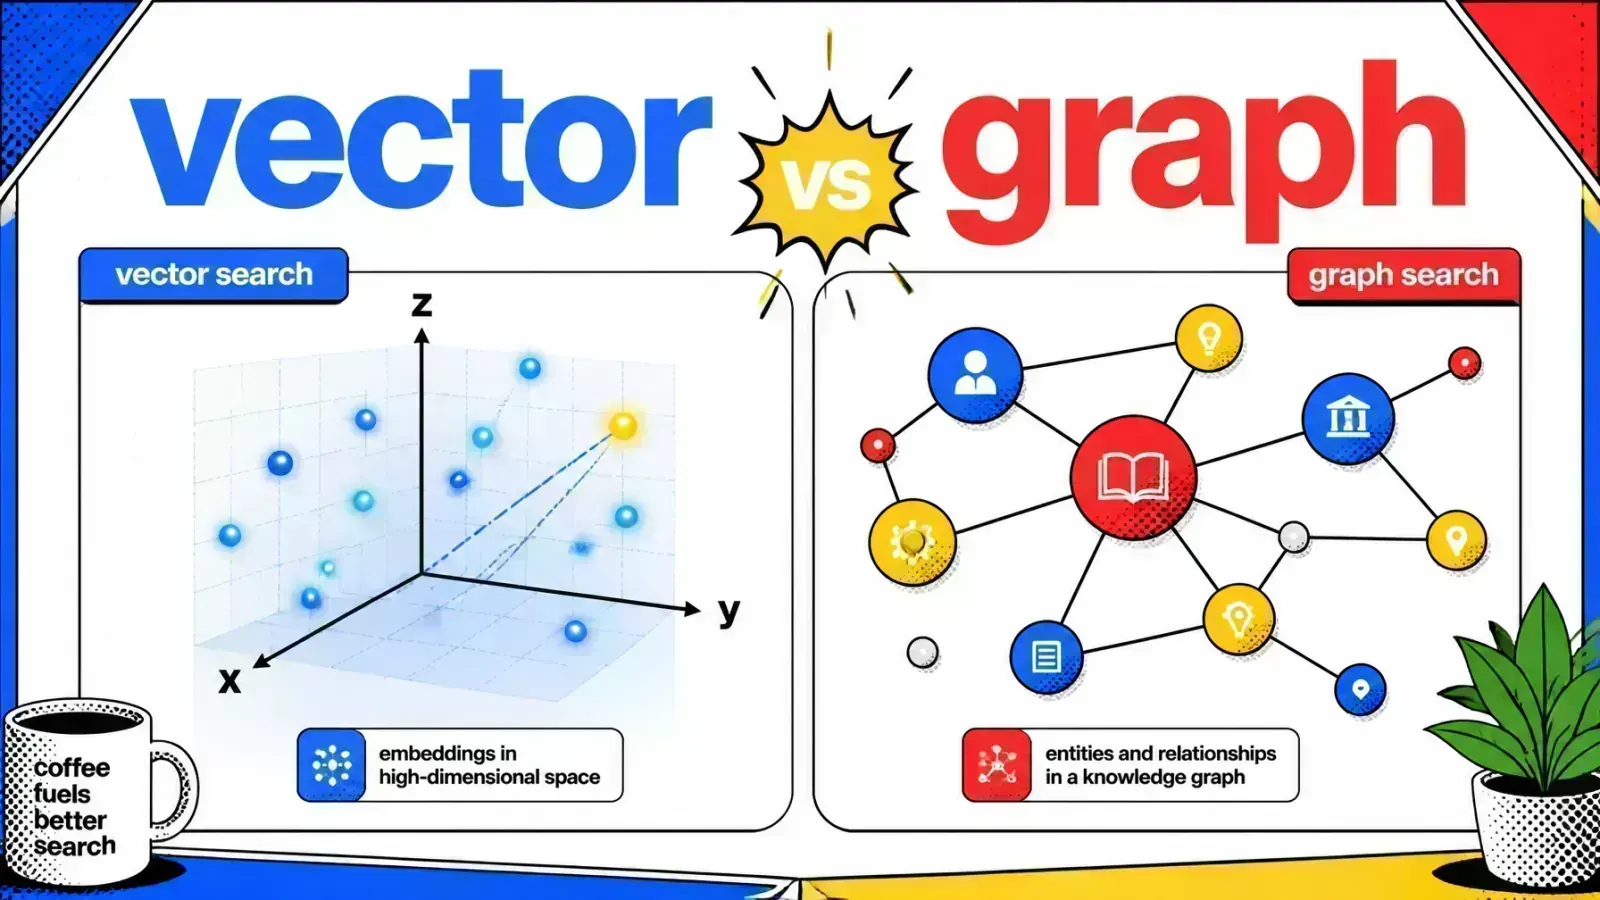
Vector search vs graph search for RAG
Compare vector search and graph search for RAG. When to use embeddings via pgvector vs relationship-based knowledge graphs, and why GraphRAG often wins.
Read post →
-
 AI
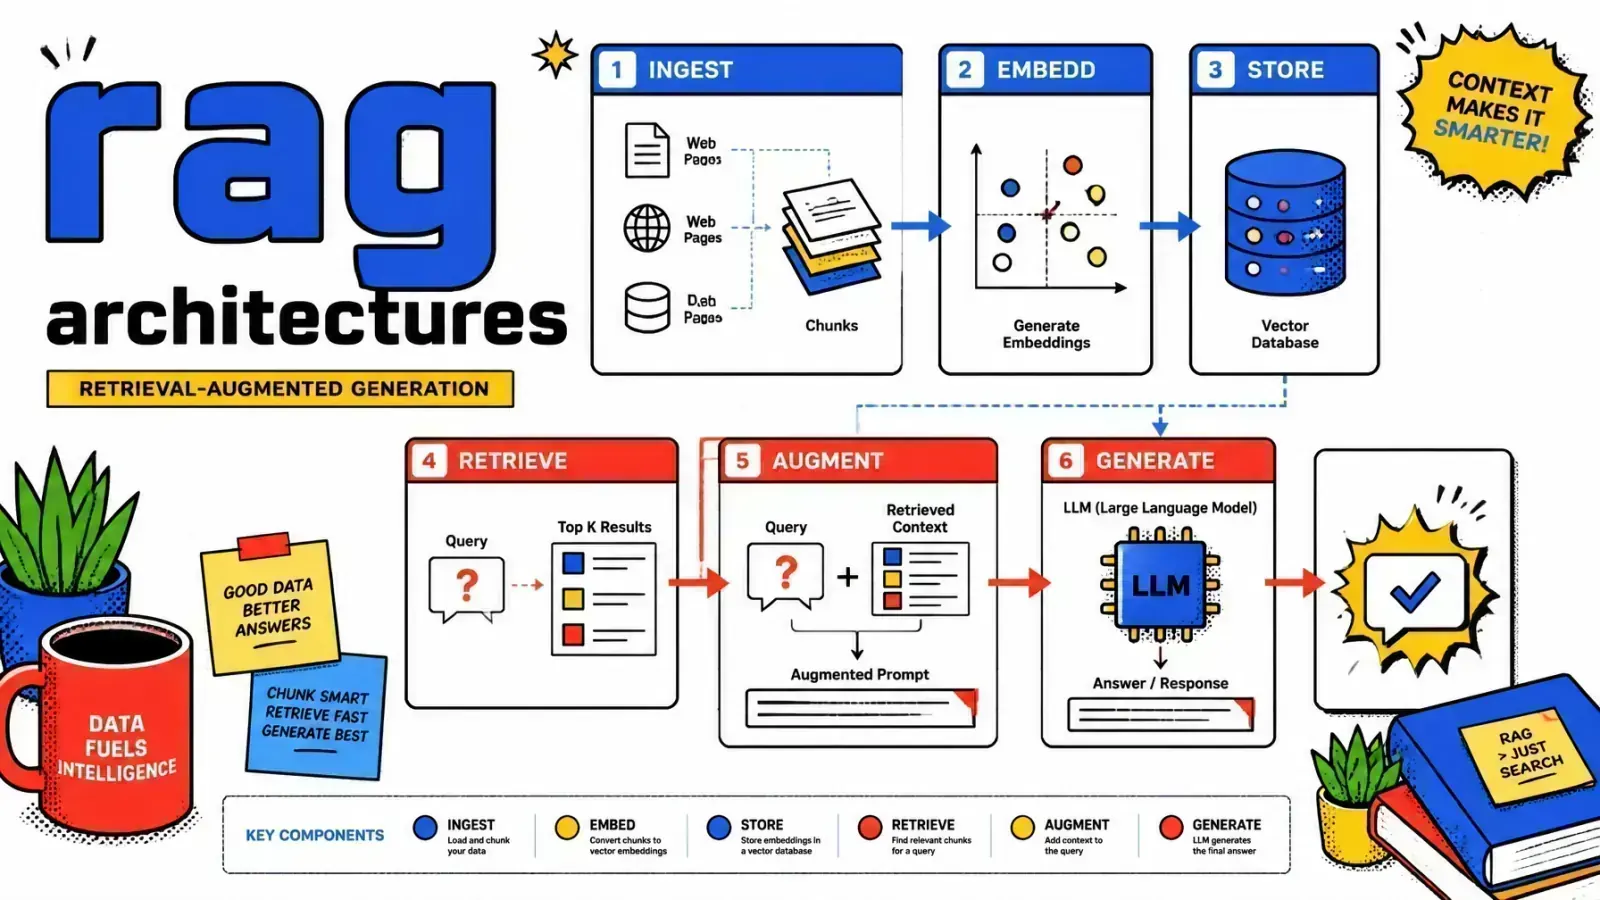
RAG architectures: traditional, agentic, corrective
Compare traditional, agentic, and corrective RAG architectures, with the latency, cost, and accuracy trade-offs that decide which fits your AI app.
Read post →
-
 AI
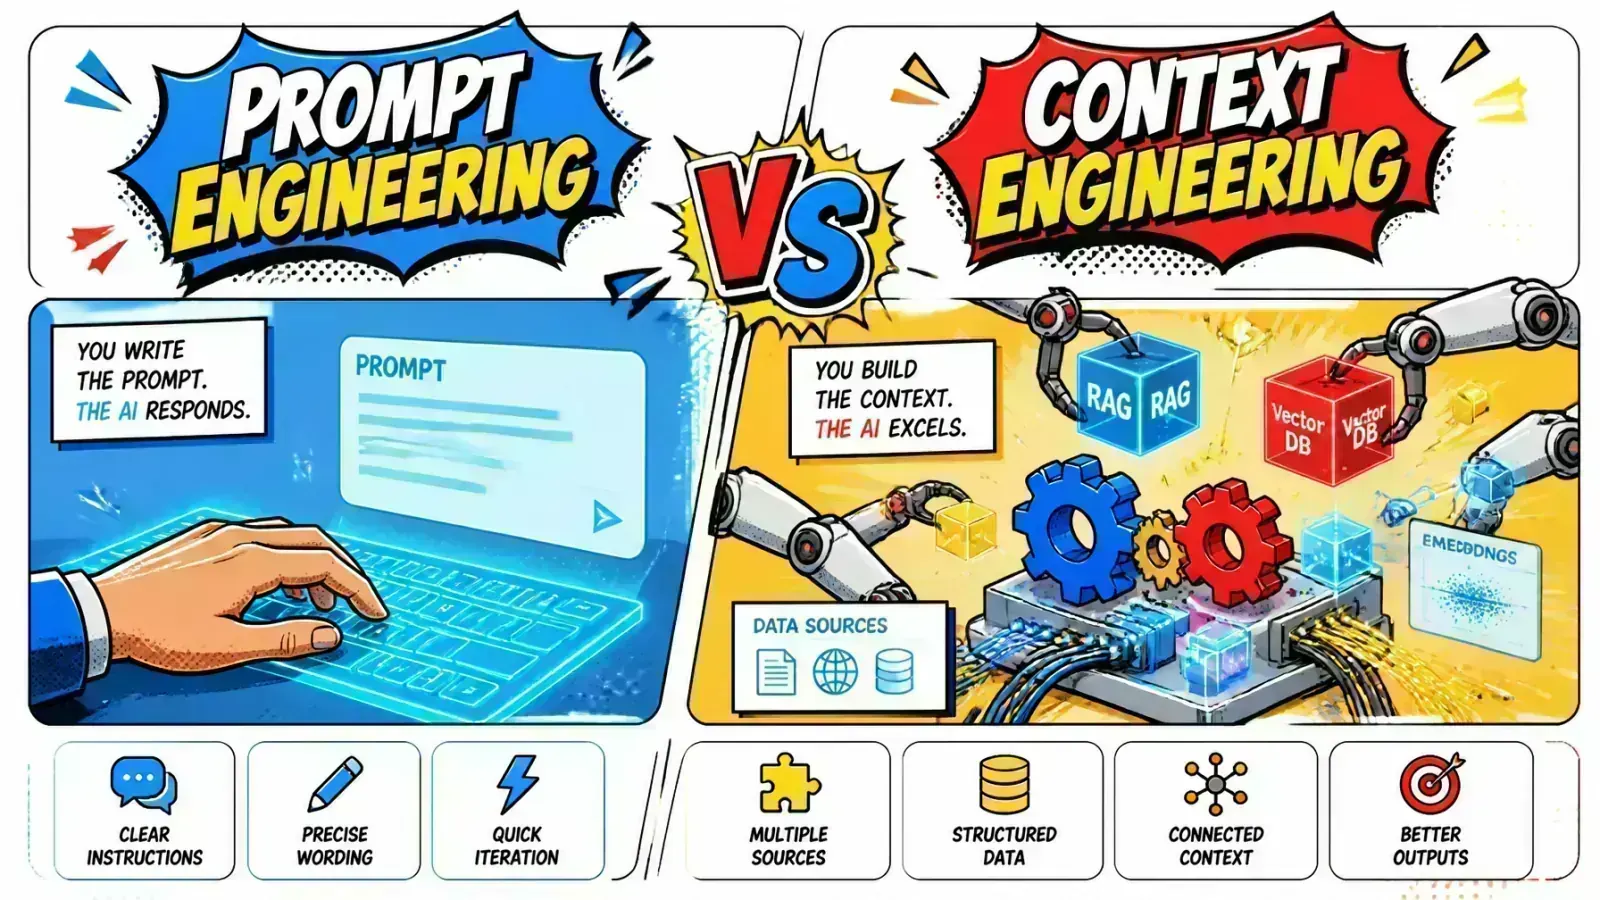
Prompt engineering vs context engineering
The shift from instruction design to data infrastructure: how context engineering uses RAG, MCP and memory to build accurate AI systems.
Read post →
-
 Architecture
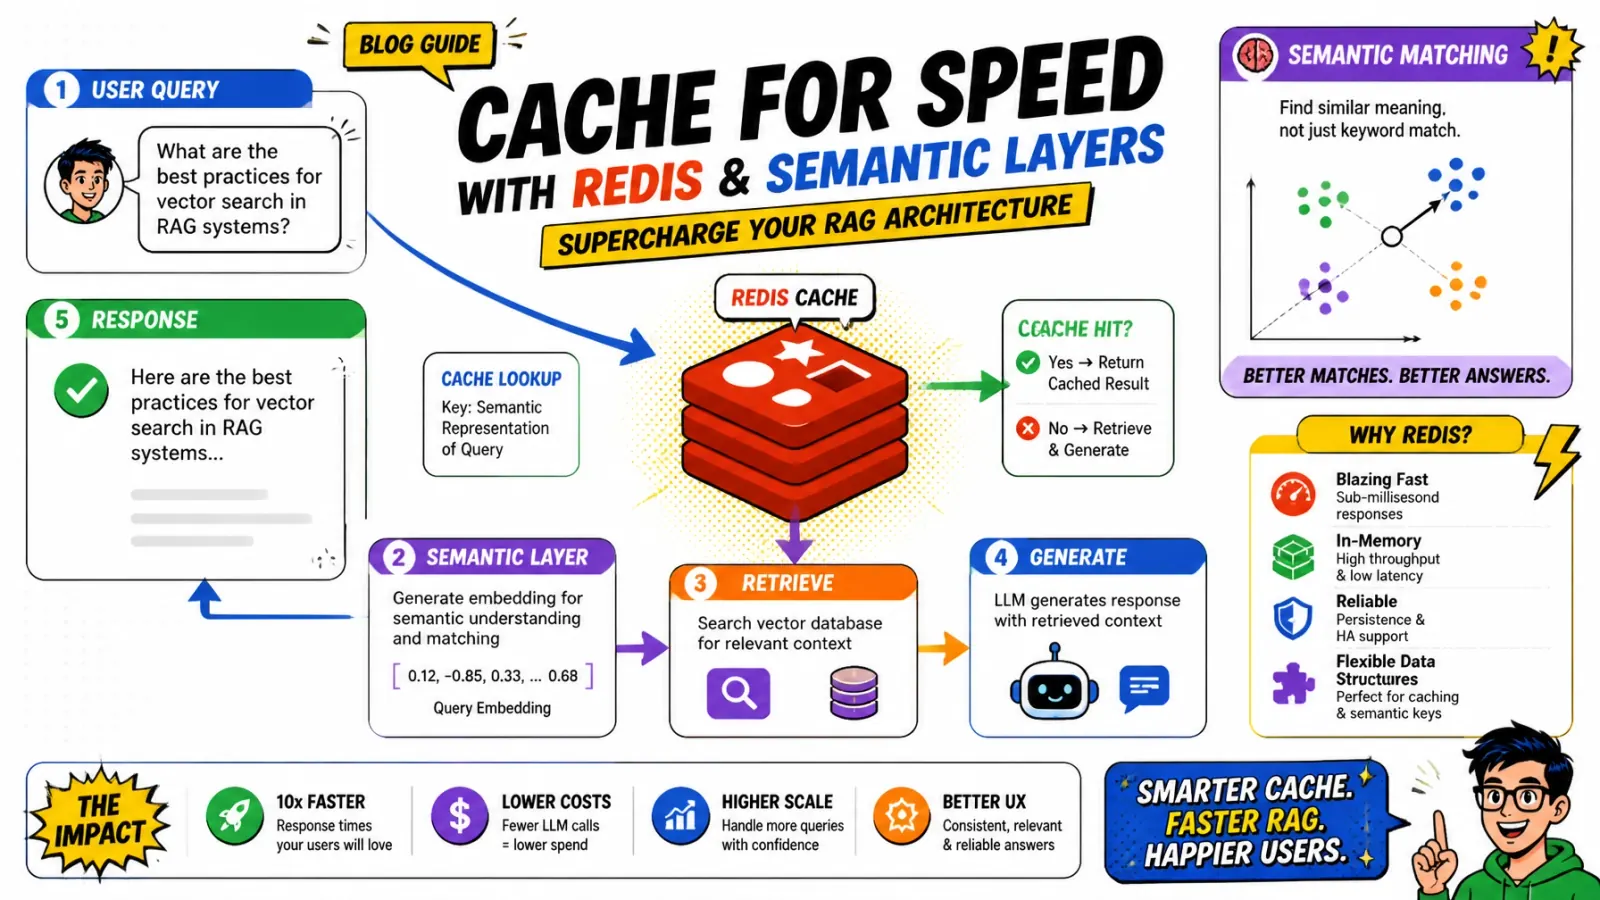
Caching for speed: Redis and semantic layers in RAG
Stop paying for the same LLM call twice. Two-tier caching with Redis keys and RedisVL semantic lookups slashes RAG latency and trims your LLM API bill.
Read post →
-
 Architecture
Circuit breakers: stopping vector DB failures
A slow vector DB kills SaaS faster than a dead one. The circuit-breaker pattern for AI infra: states, fallback tiers, and Laravel-friendly wiring.
Read post →
-
 AI
Why your RAG implementation is failing in production
Vector-only retrieval quietly breaks production RAG. Hybrid search, BM25, rank fusion, re-rankers and evals: the fixes that make it reliable.
Read post →
-
 AI
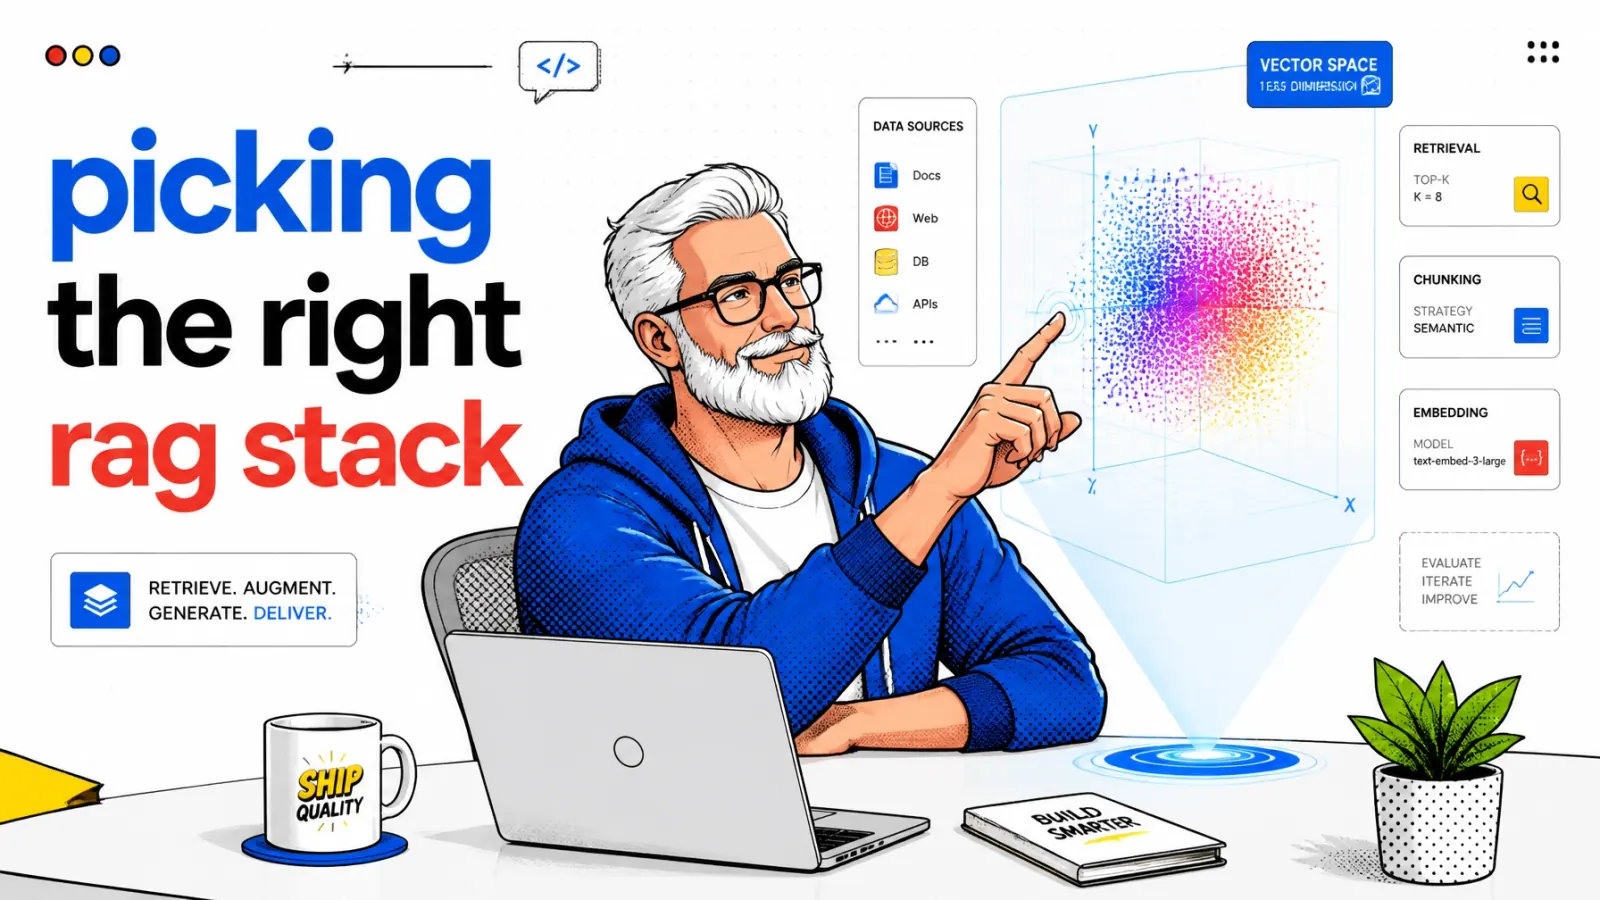
Picking the right RAG stack: vector databases for AI
pgvector, Pinecone, Weaviate, Qdrant: a 2026 field guide to picking the right vector store for your AI app, with hybrid search and scaling tips.
Read post →