DNS was built for servers that live for years. Your containers live for minutes.
You deploy a new version of your microservice and the old containers are killed instantly. You update your internal DNS records to point to the new IP addresses.
However, for the next five minutes, your API gateway continues to send 40 percent of your traffic to the dead containers. Your logs fill with connection timeouts and your error rate spikes.
This is the classic DNS staleness trap that plagues modern distributed systems.
The problem lies in how we locate resources. In a modern cloud environment, servers might only live for minutes. Relying on static naming for high-churn infrastructure creates a gap between where your traffic goes and where your healthy services actually live.
This article explores the technical differences between DNS vs service discovery, why the distinction matters for your uptime, and how to choose the right strategy for your DevOps architecture.
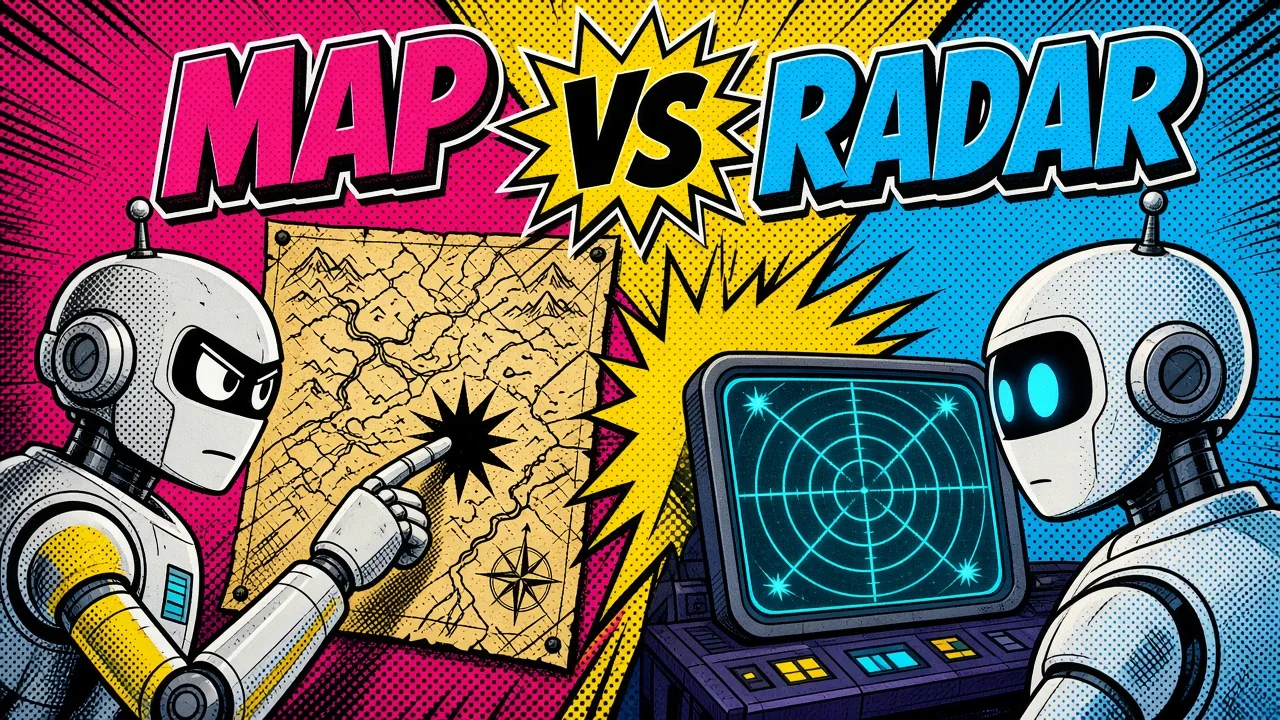
DNS vs service discovery: the map and the radar
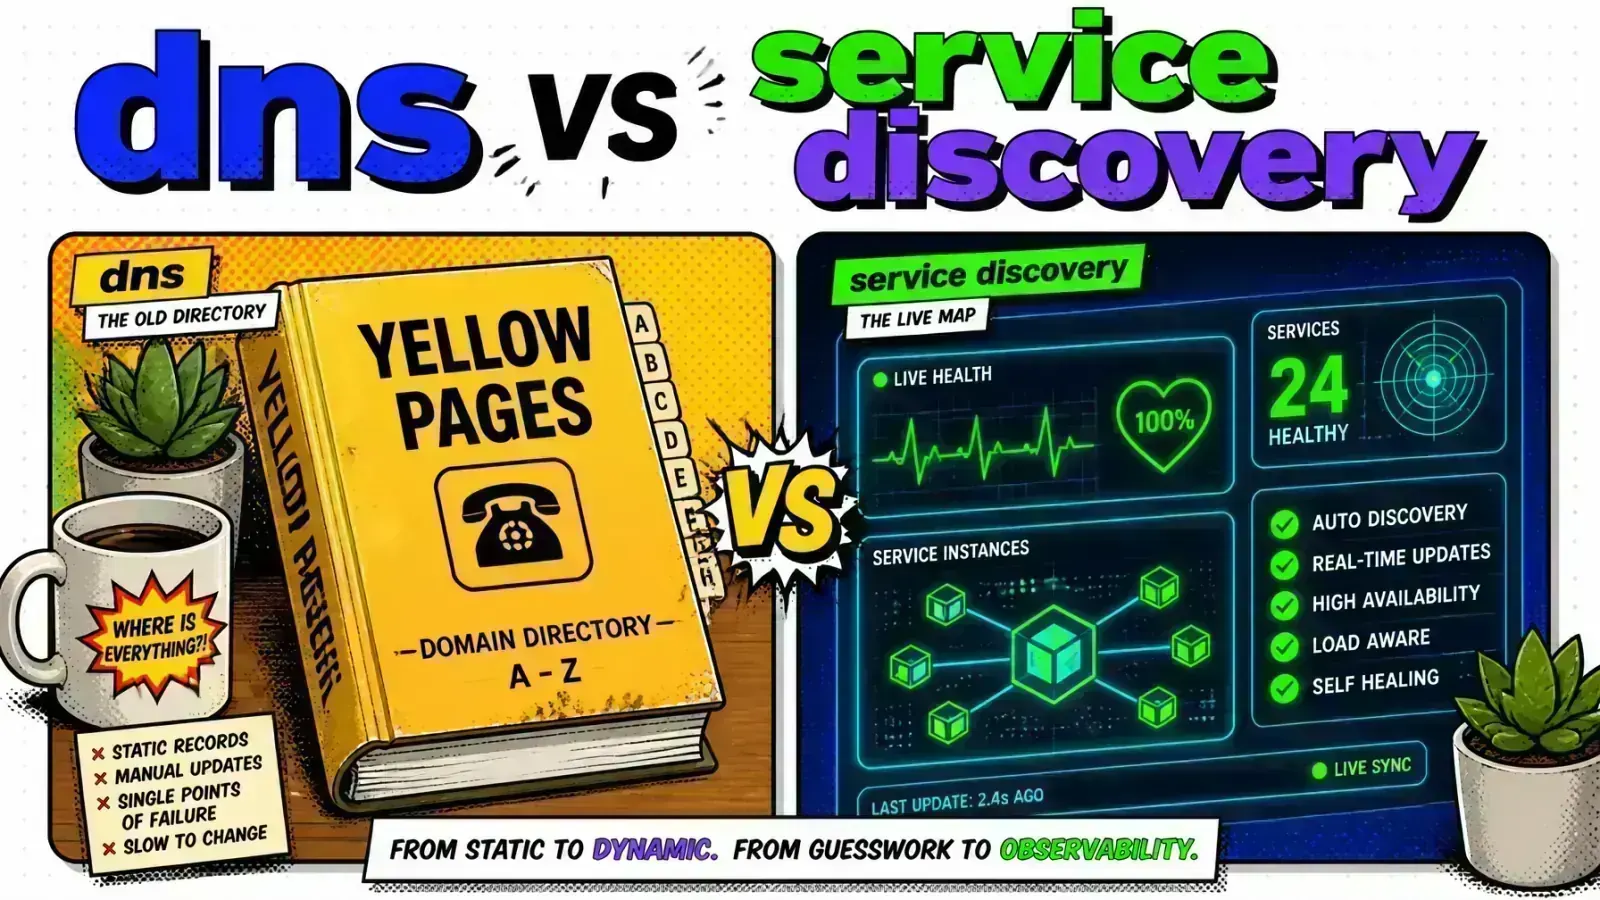
At its core, DNS is a distributed, hierarchical naming system. It acts like the Yellow Pages for the internet. You give it a hostname, and it returns an IP address.
It is very efficient and available everywhere. Every programming language and operating system knows how to talk to it.
Service discovery is a more specialized control plane. Instead of a static map, it acts like a live radar. It tracks the current state of every service instance in your cluster.
The service catalog
A service discovery system like Consul, or the internal registry in Kubernetes, maintains a “service catalog.” This catalog is a live database of every running instance.
When a new container starts, it registers itself with the catalog. When it shuts down, it is removed. This happens in milliseconds, far faster than traditional DNS propagation.
The TTL problem and DNS caching
The biggest hurdle in using DNS for microservices is Time-To-Live (TTL). DNS relies on caching so that every request does not hammer the name servers.
Your operating system caches the result. Your browser caches the result. Your API gateway caches the result.
Low TTLs are not a fix
If you set a high TTL, your service changes are slow to propagate. If you set a very low TTL (like 0 or 1 second), you might overwhelm your DNS server with lookups.
Even worse, some runtimes ignore the TTL entirely. The JVM, for example, caches a successful lookup for 30 seconds by default and forever when a security manager is set, so it can keep a stale IP until the process restarts.
| Feature | DNS | Service Discovery |
|---|---|---|
| Primary Goal | Human-readable name to IP | Dynamic instance tracking |
| Propagation | Slow (TTL dependent) | Near-instant (Gossip/Streaming) |
| Metadata | Very limited (TXT records) | Rich (tags, version, region) |
| Client Support | Native in all OS | Often requires API/Agent |
| Health Awareness | None (Static) | Active monitoring |
Push instead of wait
Service discovery solves this by moving away from deep caching. Clients or load balancers often keep a streaming connection to the registry.
When a service instance moves, the registry pushes a notification to all subscribers. There is no waiting for a cache to expire. The system converges on the new state almost instantly.
Health awareness: the core difference
A standard DNS server does not know whether the IP addresses it returns are healthy. If a server rack loses power, the DNS record still points to those IPs.
You have to update the record by hand or run a custom script to change it.
Plain DNS
Service discovery
Health checks as a first-class feature
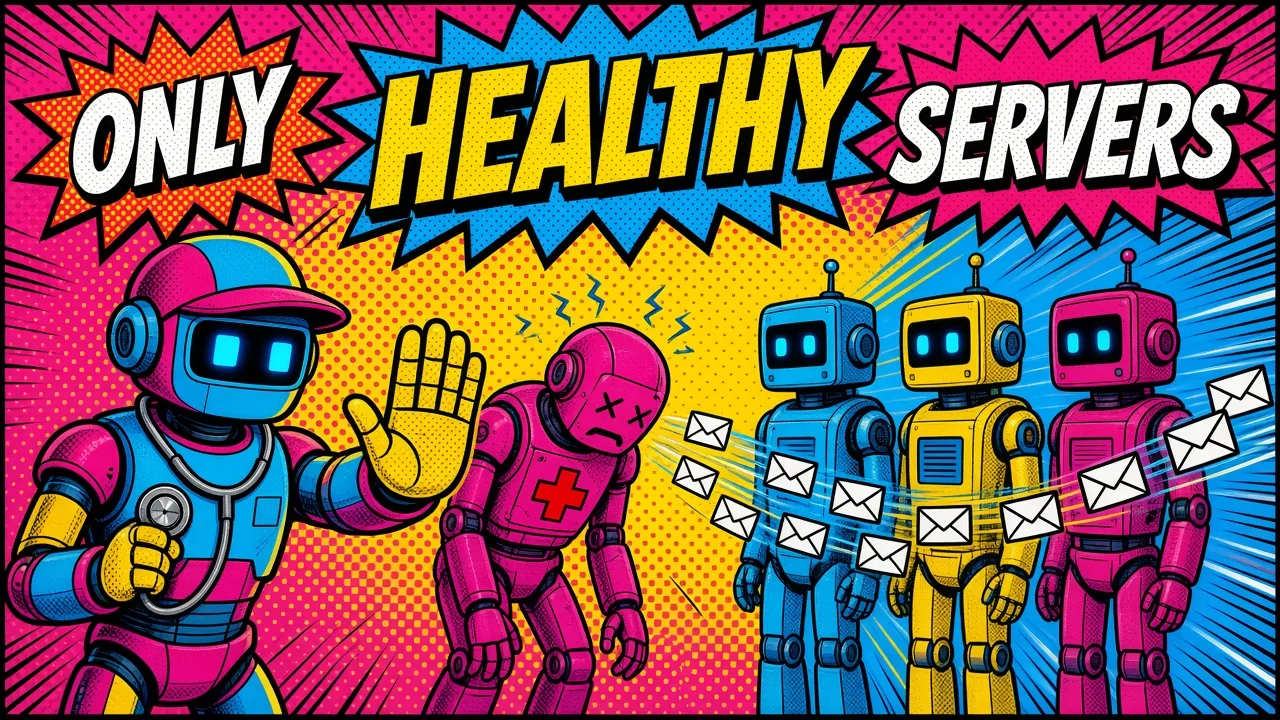
Service discovery systems run active health checks on every registered instance. A check can be as simple as a TCP probe or as complex as a custom HTTP endpoint that checks database connectivity.
If a health check fails, the instance is marked “unhealthy” in the registry. The discovery system then stops returning that IP address to clients.
This gives you a level of self-healing that plain DNS cannot, and it pairs naturally with the signals you already collect through logging and monitoring.
If you are hosting a SaaS on Docker, automated health-aware routing is the difference between a minor blip and a major outage.
Metadata and rich discovery
DNS is built to return one type of data: an IP address. You can use SRV records for port numbers or TXT records for strings, but the interface is clunky. It does not support complex queries.
Service discovery allows metadata-driven routing. You can ask the registry for “all healthy instances of the ‘orders’ service running version 2.1 in the ‘us-east-1’ region.”
Deployment patterns it enables
- Canary Deployments: Routing only 5 percent of traffic to a specific version tag.
- Blue/Green Deployments: Swapping traffic between service sets by changing a metadata flag.
- Locality-Aware Routing: Directing traffic to the instance physically closest to the requester to reduce latency.
This level of detail is essential for scaling complex systems where simple round-robin load balancing is not enough.
How modern orchestrators bridge the gap
In Kubernetes, you still use DNS names to talk to services. You might call http://order-service.default.svc.cluster.local. Does this mean Kubernetes just uses DNS?
Not exactly. Kubernetes uses a hybrid approach. It runs CoreDNS, but CoreDNS is not backed by static zone files. It is plugged directly into the Kubernetes API.
CoreDNS watches the API
When a Pod starts or dies, the control plane updates the Service and EndpointSlice objects. CoreDNS watches those objects through the API and updates its answers in real time.
For a normal ClusterIP Service, the name resolves to one stable virtual IP, and kube-proxy updates the routing behind it as Pods come and go. For a headless Service, the name resolves straight to the current Pod IPs.
In this model, DNS is just the “wire protocol.” It is the interface your application uses because it is easy and standard. The backend is a fully dynamic service discovery engine.
That gives you the simplicity of DNS and the speed of service discovery.
Implementation strategies: when to use which?
Choosing between DNS vs service discovery depends on your infrastructure scale and churn rate.
If you run a monolithic application on a few virtual machines that rarely change, DNS is perfectly fine. You can manage your records with simple automation or even by hand. A dedicated discovery system would cost more than it gives back.
If you use containers, serverless functions, or microservices, you need a dynamic solution. If your IPs change every time you deploy or scale, DNS will eventually break your traffic flow.
A DNS interface on a dynamic registry
For many developers, the best path is a tool that provides a DNS interface on top of a dynamic registry. HashiCorp Consul is a popular choice for this.
It lets you query the registry with a standard DNS lookup, while it handles the health checking and registration logic behind the scenes.
Key takeaways
- DNS is for stability: Use it for external traffic, long-lived resources, and cross-company communication where caching is an advantage.
- Service Discovery is for churn: Use it for internal microservices, containers, and autoscaling groups where instances appear and disappear frequently.
- Mind the Cache: Never rely on plain DNS for sub-minute failover because client-side caching will almost always outlive your records.
- Health is Binary: Without active health checks, your discovery system is just a list of guesses. Always integrate automated liveness and readiness probes.
- Hybrid is Best: Use a discovery engine (like Kubernetes or Consul) that exposes a DNS interface. This simplifies your application code while keeping your infrastructure dynamic.
If you’re untangling service routing for a high-churn stack, here’s how I help teams ship it.
When was the last time a stale DNS record caused a production incident in your environment?